

CutSeq is a library-aware wrapper for cutadapt. Real NGS libraries need several trimming steps performed in the correct order — encoding them all in one cutadapt command is error-prone, and chaining separate commands wastes I/O. CutSeq fixes this with a single input: what the library looks like. It compiles your library scheme into one native cutadapt pass and runs it automatically.
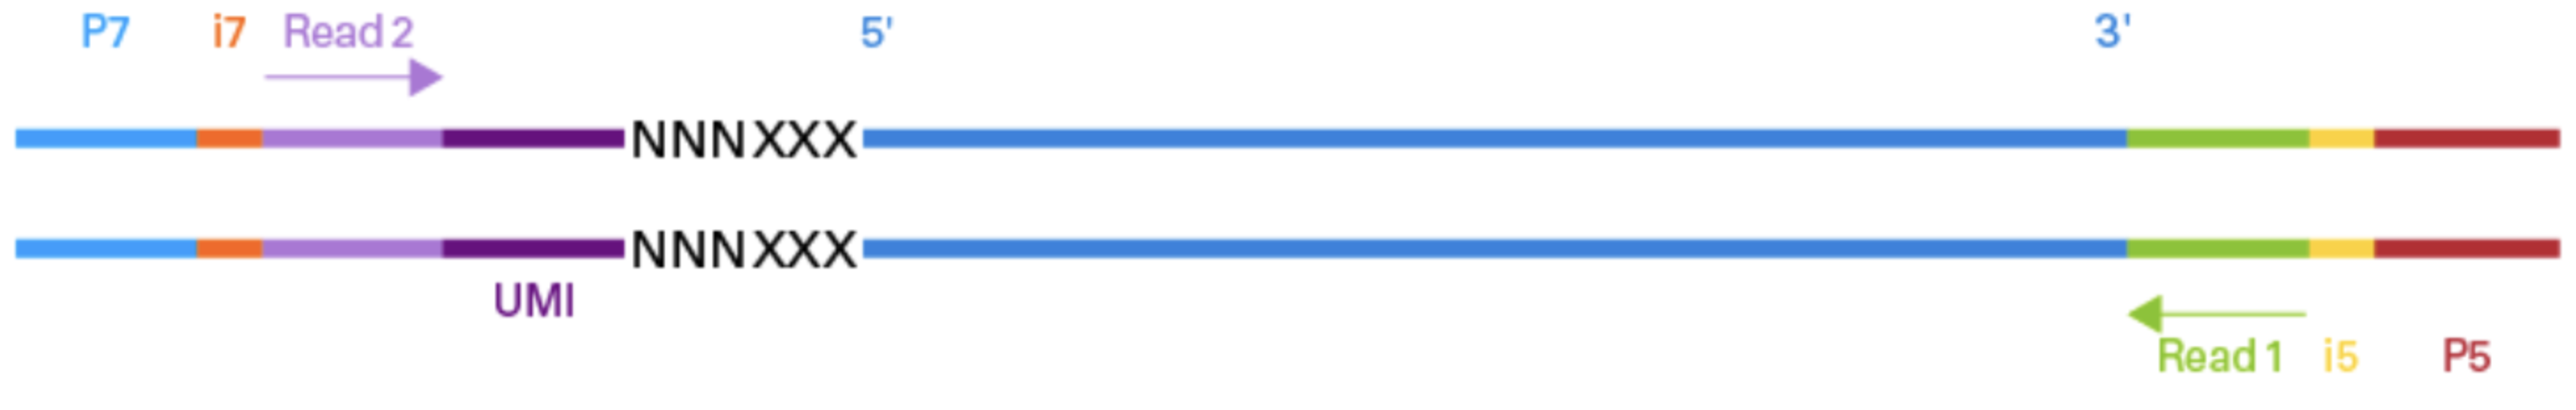
Take SMARTer® Stranded Total RNA-Seq Kit v3 (built-in TAKARAV3) — many
operations in one pass:
| Read | Steps |
|---|---|
| R1 | remove the 5′ p5 adapter + 3-nt linker mask · capture the 8-nt UMI & mask the 6-nt linker at the 3′ end (the 14-nt run-over when insert < read) · remove the 3′ read-through adapter · quality trim |
| R2 | remove the 5′ read-through adapter · extract the 8-nt UMI into the read name · mask the 6-nt linker right after it · remove the 3′ read-through adapter · quality trim |
pip install cutseqExpress the whole library as one scheme and let CutSeq do the rest:
# built-in scheme
cutseq -A TAKARAV3 test_R1.fq.gz test_R2.fq.gz

# or a custom grammar scheme
cutseq -A "ACACGACGCTCTTCCGATCTXXX-XXXXXXNNNNNNNNAGATCGGAAGAGCACACGTC"
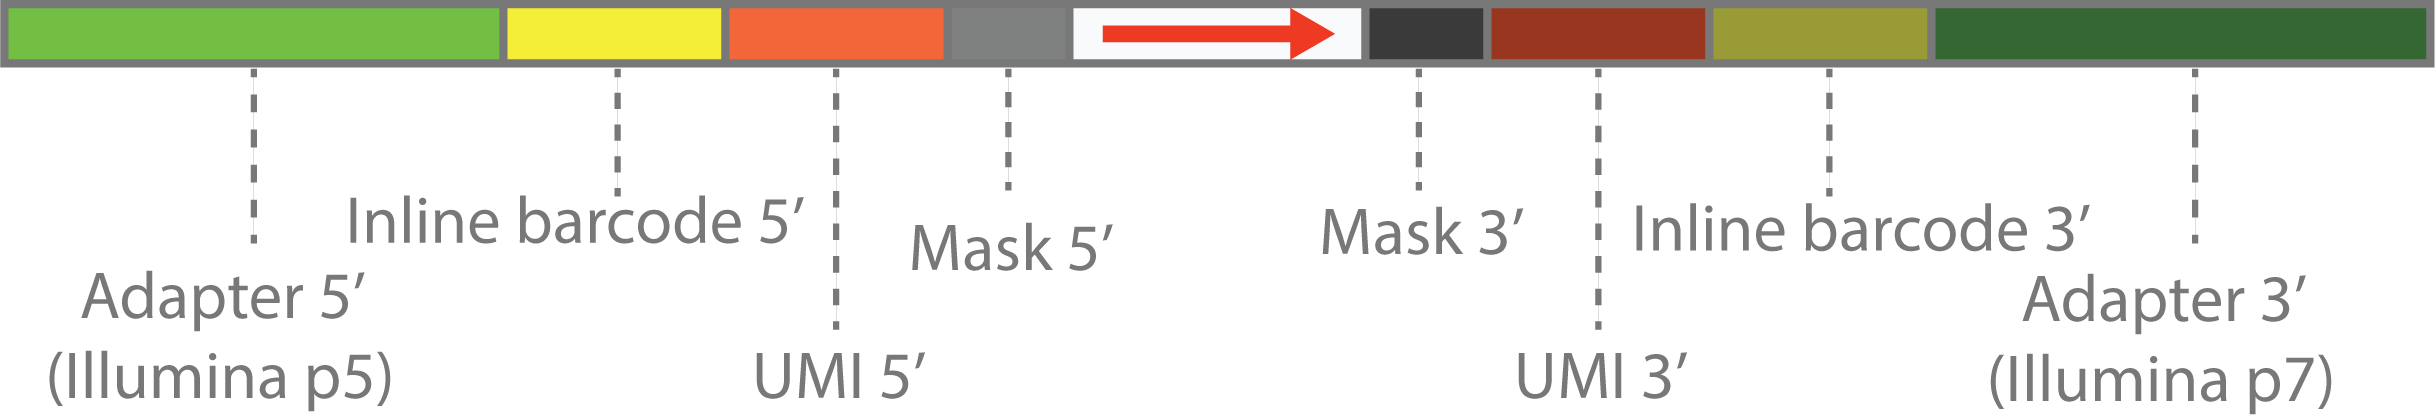
The scheme is a top-strand molecular map: one DNA strand, 5′ → 3′, no spaces:
- The part left of the insert marker (
+-:) is read by R1 as-is; the part right of it is the molecule's 3′ continuation and is matched on R2 as its reverse complement automatically (e.g. a right-handAGATCGGAAGAGCACACGTCis matched on R2 asGACGTGTGCTCTTCCGATCT). += sense,-= antisense,:= unstranded.- Lowercase
acgt…= a read-external sequencing-primer / flowcell region: it is NOT part of the read, so the read starts after it (the scheme's read boundary). This is the confirmed grammar rule — a lowercase ACGT run is skipped, never captured or trimmed. - Uppercase
ACGT…(between the two lowercase edges) is the read-internal insert region: a fixed uppercase run directly adjacent to a lowercase edge is an inline barcode (matched & captured), while an uppercase run not adjacent to a lowercase edge is an adapter (matched & trimmed). N= random UMI, captured into the read name (NNNNNNNN/N8).X= masked sequence, trimmed but not captured (XXXXXX/X6); this is the only non-sequence character class besidesN(both uppercase).- Case may not be mixed inside one contiguous feature: lowercase and
uppercase blocks must be cleanly separated (
lower|upper|lower|upper…). A run that flips case more than once (e.g.ACtaGT,nnAGCnn) is rejected with a clear error. - Homopolymer tails use the dot form
AAA...AAA/TTT...TTT/GGG...GGG; the 5′/3′ direction is auto-detected from the scheme layout (a run at the read start trims the 5′, elsewhere the 3′), andG<k>sets the minimum run length (e.g.G10). - A 3′ read-through adapter (from the other read's 5′ arm) is trimmed automatically from the opposite end of each read.
- Numeric shorthand (
N8,X6) equals the expanded run form.
The scheme is a top-strand molecular map (5′ → 3′, no spaces); the case of a base run sets its role:
- Lowercase
acgt…= a read-external sequencing primer / flowcell / outer edge. It is NOT part of the read, so the read starts after it — the run is skipped, never matched, captured or trimmed. This is what replaced the old--r1-primer/--r2-primer/--seq-primer1/--seq-primer2flags (now removed). - Uppercase
ACGT…(between the two lowercase edges) = the read-internal insert region. A fixed uppercase run directly adjacent to a lowercase edge is an inline barcode (matched & captured); any other fixed uppercase run is an adapter (matched & trimmed). N…/N<k>= UMI capture (into the read name);X…/X<k>= mask (trimmed, not captured). Both must be uppercase.- Case may not be mixed inside one feature: lowercase and uppercase blocks must be cleanly separated (
lower|upper|lower); a run that flips case more than once (e.g.ACtaGT) is rejected with a clear error.
# lowercase read-1 primer … skipped (read starts after it); N11 = 11-nt UMI
# (captured, padded with N if short), X5 = 5-nt mask; +XX = reverse-complemented
# 3' mask; single-end extracts the UMI and trims the mask.
cutseq -A 'gacgtgtgctcttccgatctNNNNNNNNNNNXXXXX+XXagatcggaagagcgtcgtgt' \
  -R '{id}_umi:{1}' R1.fq.gz
The built-in primer list (cutseq --list-primers) remains as a knowledge base / diagnostic only — it never changes trimming or matching.
Captured UMIs/barcodes are appended to the read name with _ by default
(@READID_CTATTAAAAA, exactly like legacy output). By default every
captured segment — each N UMI plus each inline (lowercase) barcode, across
both arms — is concatenated in scheme written order (left / R1-arm parts
first, then right / R2-arm parts). If any required capture is missing or
incomplete the whole appended suffix is dropped (@READID_, the legacy
single-capture contract); a partial barcode is never silently padded. Use
--rename for full control — cutadapt's brace variables ({id}, {header},
{cut_prefix}, {match_sequence}, {rc}, …) plus positional captures
{1}, {2}, … in scheme order:
cutseq -A INLINE --rename '{id}_BC1:{1}_BC2:{2}_umi:rc({3})' in_R1.fq.gz in_R2.fq.gzTransform functions wrap any capture and nest (case-insensitive):
rc(x)/rev(x)/comp(x)— reverse complement / reverse / complementupper(x),lower(x),len(x)canon(x)— canonical UMI,min(x, rc(x)), for UMI collapsingleft(x,k),right(x,k),slice(x,a,b)— substring helpers
In paired mode {r1.1} / {r2.1} force a specific read; an unprefixed capture
resolves to its anchor read (left-side captures → R1, right-side → R2), so
both mates carry the same value. Unlike an explicit --rename template (whose
missing references are just empty for that slot), the default is all-or-nothing:
it only emits the combined capture suffix when every required capture is
complete on its anchor read, otherwise it emits just the read id. Explicit
label: names must be unique across the whole scheme — a duplicate (or an
auto barcode{n} that collides with an explicit label) is rejected with an
actionable error rather than silently overwritten.
Spatial libraries stack several fixed-length barcodes on one arm. In
DBiT-seq (deterministic barcoding in tissue, 50×50 grid) R2 walks
handle(22) | BarcodeB(8) | linker(30) | BarcodeA(8) | linker(30) | UMI(12) | polyT | cDNA, while R1 carries the insert with a template-switch oligo (TSO).
Everything fits in one command:
cutseq -A DBITSEQ \
  -R '{id}_BCB:{3}_BCA:{2}_UMI:{1}' \
  -O mysample R1.fq.gz R2.fq.gz
Built-in DBITSEQ scheme:
AAGCAGTGGTATCAACGCAGAGTGAATGGG...GGG : N12 AGTCGTACGCCGATGCGAAACATCGGCCAC
                                           N8  CGAATGCTCTGGCCTCTCAAGCACGTGGAT
                                           N8  AGATGCGAGAAGCCAACGCTTG
- Left of
:= R1's real read-5′ scaffold: the TSO (23 nt) then an auto-detected 5′ G-stretch (GAATGGG...GGG), both trimmed. - Right of
:= the barcode arm, walked on R2: UMIN12→ capture{1}, linker trimmed, BarcodeAN8→ capture{2}, linker trimmed, BarcodeBN8→ capture{3}, handle trimmed. The-Rtemplate writes@READID_BCB:…_BCA:…_UMI:…. M6AARTRis kept as a deprecated alias. Read boundaries come from the scheme's lowercase edges (--r1-primer/--r2-primer/--seq-primer1/--seq-primer2have been removed): a lowercase ACGT run is a read-external sequencing primer, skipped so the read starts after it.
The same library as a fully inline scheme:
cutseq -A "AAGCAGTGGTATCAACGCAGAGTGAATGGG...GGG:N12AGTCGTACGCCGATGCGAAACATCGGCCACN8CGAATGCTCTGGCCTCTCAAGCACGTGGATN8AGATGCGAGAAGCCAACGCTTG" \
  -R '{id}_BCB:{3}_BCA:{2}_UMI:{1}' -O mysample R1.fq.gz R2.fq.gz
Full construct, top strand 5′ → 3′:
P5(29) | i5(8) | R1-primer(34) | TSO(23) | insert | polyA/T | UMI(12)
| rc(L1)(30) | BarcodeA(8) | rc(L2)(30) | BarcodeB(8) | rc(handle)(22)
| rc(R2-primer)(34) | i7(8) | rc(P7)(24)
Within the read-internal insert region (between the two read-external
lowercase edges), a fixed uppercase run directly adjacent to a lowercase edge
is an inline barcode (matched & captured). An uppercase run not adjacent
to a lowercase edge is an ordinary adapter (matched & trimmed). N captures
and X masks keep their meaning. This is a structural rule — it no longer relies
on a primer database.
The built-in Illumina/BGI primer list (cutseq --list-primers) is now kept as a
knowledge base / diagnostic only: it is never used to change trimming or
matching. When a lowercase run matches a known primer, CutSeq logs
"looks like known sequencing primer …"; otherwise it logs "is not in the known
primer list; confirm it is a sequencing primer / external region".
A single -d output collects every rejected read, with the reason encoded in
the name:
cutseq -A SMALLRNA -d discarded_R1.fq.gz discarded_R2.fq.gz in_R1.fq.gz in_R2.fq.gz| Tag | Why |
|---|---|
reason=too_short |
shorter than --min-length after trimming |
reason=too_many_n |
exceeds --max-n |
reason=low_quality |
mean Phred below --min-avg-quality |
reason=no_barcode |
missing an inline barcode (with --ensure-inline-barcode) |
Without -d/-O, discard files are auto-named from the input files.
CutSeq compiles a scheme once into a lazy graph of native cutadapt modifiers (adapter cutters, renamers, quality trimmers) and runs them in a single cutadapt pass — no intermediate I/O. Each grammar token maps to a 5′/3′/ single-end emitter, and output is verified to match the legacy engine exactly across all built-in schemes, paired- and single-end.
More details: https://cutseq.yech.science
When a library's outer primers are genuine sequencing-primer binding sites
(e.g. the Illumina read-1 / read-2 primers), write them as lowercase runs.
CutSeq treats a lowercase ACGT run as a read-external region: the read starts
after it (it is absent from the FASTQ), so the run is skipped — never captured
or trimmed. Such a scheme is routed through a read plan: R1 begins downstream
of the lowercase read-1 edge (the first N/X/poly run after it is cut
unconditionally), R2 begins at its lowercase read-2 edge, and the mirrored
read-through cuts fire only when that arm really was sequenced — never because
it happens to be long.
# gacgt…   lowercase = the read-1/read-2 sequencing primers, upstream & skipped.
# N11 X5   = UMI capture {1} + 5-nt mask, then the insert; +XX = Kappa 3' mask.
# Single-end extracts the 11-nt UMI and trims the mask, with no primer flag.
cutseq -A 'gacgtgtgctcttccgatctNNNNNNNNNNNXXXXX+XXagatcggaagagcgtcgtgt' \
  -R '{id}_umi:{1}' R1.fq.gz
A library whose outer adapters are ordinary read-visible scaffolds (e.g. the
legacy all-uppercase DBiT / INLINE schemes) is unchanged: those uppercase
adapters stay in the read and are trimmed as normal (no lowercase edge → no read
boundary). A lowercase run that is ambiguous (resolves to multiple distinct
boundaries) fails actionably. The primer list (cutseq --list-primers) is a
diagnostic only — it is never used to change the read boundary.
- support more library schemes